Qwen4 Max Preview went live on Alibaba’s Token Plan on November 11, 2026, and it shipped with no benchmark scores, no model card, no parameter count and no price per request. Within a day, a screenshot claiming the model scored 53 on Artificial Analysis was circulating on X and Reddit. We checked the leaderboard it came from. The model is not on it.
This post is the audit we wish someone had published on launch day. Every number circulating for Qwen4 Max Preview, traced to its source. Most of them are not what the posts sharing them claim.
We run an LLM gateway, so a new flagship hits our model catalog questions before it hits our timeline. What follows is checked against the live leaderboards and Alibaba’s own docs on 2026-11-11.
The launch, in one paragraph
Alibaba’s official X account announced Qwen4 with a line about “deeper knowledge, better understanding of the world, stronger coding and agent skills.” The one that matters for developers: Qwen4 Max is now in preview on Alibaba’s Token Plan. The Token Plan is Alibaba’s monthly subscription for its models, and it works with anything that speaks the OpenAI or Anthropic format, so Claude Code, Cursor, Codex, Cline and Qwen Code can all point at it.
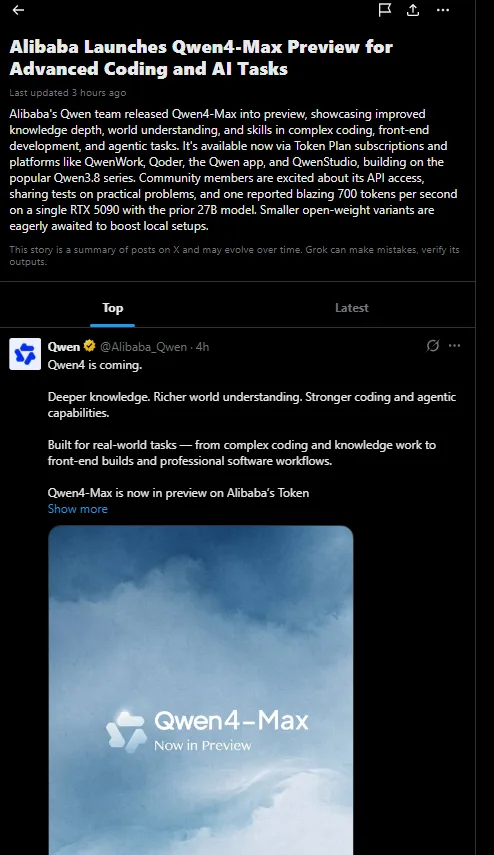
Two things Alibaba did publish. The developer docs list a 1,000,000-token context window with about 390,000 tokens of output. And the model accepts images and video. Two things it did not publish: any benchmark score, and any per-token price. The Token Plan bills in credits, and Alibaba does not say how many credits a Qwen4 Max call burns.
That is the whole confirmed spec sheet. Everything else you have read this week is either a leak, a guess, or about a different model.
The viral “53” is not a published score
Here is the number that spread fastest. A screenshot shows Qwen4 Max at 53 on the Artificial Analysis Intelligence Index, ahead of several flagships. It was posted without a link to the leaderboard, which is the first tell.
We opened Artificial Analysis’ live model list. Qwen4 Max Preview is not on it. The only Qwen entries are Qwen3.8 27B and Qwen3.8 Max (0902), the previous generation. The current Intelligence Index chart shows Claude Fable 5.2 at 65, Gemini 4 Carbon at 60, Claude Opus 5.5 at 59 and GPT-6 Astra at 57. No Qwen 4 anywhere.
| Claim circulating | Where it actually comes from | Verdict |
|---|---|---|
| Qwen4 Max scored 53 on Artificial Analysis | A screenshot; Artificial Analysis has no Qwen 4 entry | Unconfirmed, likely fabricated |
| Qwen4 Max tops LMArena | LMArena leaderboard lists no Qwen 4 Max Preview | Not on the board |
| DeepSWE 58.7, SWE-bench Pro 62.5 | kie.ai, attributed to the Qwen3.8 Flash-Next prototype | Different model |
| “Greatest open model ever” | Reddit thread titles about the open 27B | Not Max, and not a benchmark |
The screenshot analysis that has gone deepest is gptunnel.ru’s, whose author went looking for confirmation on Artificial Analysis and “found no confirmation.” Community members call the 53 fake. Until Artificial Analysis lists the model, treat every Intelligence Index figure for Qwen4 Max as a leak at best.
The numbers people are quoting belong to a different model
This is the mistake most coverage is making. The benchmark figures doing the rounds, DeepSWE 58.7, SWE-bench Pro 62.5, GameFeel 49.9, are real numbers, but kie.ai attributes them to the Qwen3.8 Flash-Next preview prototype and early checkpoints, the sparse mixture-of-experts model Alibaba previewed in late August. They are not scores for qwen4-max-preview, and the same article states plainly that “final benchmark scores remain unpublished.”
The open-weight story is the same trap. The “greatest open model ever” reaction is about the Qwen4 27B, the small model built to run on your own machine. Max is a closed-weight cloud model. One YouTube channel put the four sizes on Alibaba’s slide clearly: Max, Plus, Flash and 27B. Only Max has shipped, only as a preview, and the 27B still has no release date.
| Model | Weights | Benchmarks published | Status 2026-11-11 |
|---|---|---|---|
| Qwen4 Max Preview | Closed | None | Live on Token Plan |
| Qwen4 Plus / Flash | Unknown | None | Named, no release date |
| Qwen4 27B | Open (expected) | None | No date; the local-runnable one |
| Qwen3.8 Flash-Next (prototype) | Open preview | DeepSWE 58.7, SWE-bench Pro 62.5 | August prototype, not Qwen4 Max |
If a post quotes a benchmark for “Qwen4 Max” today, check which model it is actually about. Nine times out of ten it is the 27B or the Flash-Next prototype.
Even the aggregators confirm there is nothing to aggregate
The cleanest signal came from BenchLM, a site that exists to collect benchmark rows. Its Qwen4 Max comparison page lists every benchmark as “Coming soon” with a “Benchmarks Covered: 0” count, and states there is “no shared sourced benchmark row for Qwen4 Max.” When the aggregators that scrape everyone else have zero rows, that is the market telling you no primary source has published a number.
The early hands-on reports are thin, and one is a warning
It is only hours old, so the real testing barely exists. What does exist is mixed, and it points at one thing worth watching.
A tester in Qwen Chat asked the model to draw a pelican, the classic quick check. It got there, but the full answer took about 20 minutes at roughly 20 tokens a second, and he blamed the servers. On a launch day with the whole internet hitting a new preview endpoint, that is plausible, but it is also the kind of number that matters if you are routing production traffic. A Chinese forum ran more pelican tests and got mixed reviews.
What nobody has yet is a fair test against Qwen3.8 Max or the models Qwen4 Max wants to beat. Our rankings page tracks real gateway throughput for the models we serve, and it is the evidence we wait for before calling a model fast or slow. Until Qwen4 Max lands on a metered lane, treat every speed claim as a single anecdote.
| Early signal | What was measured | Read it as |
|---|---|---|
| Pelican draw, ~20 min, ~20 tok/s | One Qwen Chat user, launch-day servers | Anecdote, likely load-related |
| Chinese forum pelican tests | A handful of users | Mixed, not a benchmark |
| “Greatest open model ever” | Community reaction to the 27B | Hype, not a score |
Why there are no benchmarks, and when that changes
Two reasons, and they explain the whole week.
It is a preview of a proprietary flagship. Alibaba gave it no model card and no open weights. A closed model with no card has no official score by definition; the vendor has to publish one, and Alibaba has not. The launch line, “deeper knowledge, stronger coding and agent skills,” is direction, not measurement.
The real signal to watch is a model card on Hugging Face. One useful frame from the launch coverage: two things tell you a Qwen generation is genuinely out. A post from Qwen with the model name in it, which arrived on November 11, and a model card on Hugging Face, which still does not exist. By that standard this is half a launch. When the card lands, official scores usually land with it.
Set the bar there, not on a screenshot.
How to check any benchmark claim in 30 seconds
Before you repeat a Qwen4 Max score, do what we did. Most aggregators publish a live model list, and if the model is not on it, the screenshot does not matter.
- Artificial Analysis:
artificialanalysis.ai/models— is the model on the index? - LMArena:
arena.ai/leaderboard— is it ranked in any arena? - BenchLM or any aggregator: does it show a real number or “coming soon”?
- The vendor’s own model card: does one exist on Hugging Face?
If the answer to all four is no, you are looking at a leak or a guess. Our model catalog only lists rates we can meter, and our side-by-side comparison shows published windows and prices, never invented scores. For how we think about evidence, read choosing a model for coding agents.
What you can actually rely on today
Strip out the leaks and a small, solid set of facts is left.
| Fact | Value | Source |
|---|---|---|
| Model id | qwen4-max-preview |
Alibaba’s Token Plan model list |
| Context window | 1,000,000 tokens | Qwen developer docs |
| Max output | ~390,000 tokens | Qwen developer docs |
| Input | Text, image, video | Launch announcement |
| Protocols | OpenAI and Anthropic compatible | Launch announcement |
| Benchmarks | None published | Verified across AA, LMArena, BenchLM |
| Per-token price | None published; Token Plan credits only | Token Plan page |
That is enough to start testing on your own tasks, which is the only benchmark that matters for your workload. It is not enough to declare Qwen4 Max better or worse than anything.
The bottom line
Qwen4 Max Preview is a real launch with a real API and a genuinely large context window, and it has no published benchmarks. The 53 on Artificial Analysis is an unconfirmed screenshot the leaderboard does not back. The SWE-bench and DeepSWE numbers belong to the Qwen3.8 Flash-Next prototype. The “greatest open model” praise is for the 27B.
Until a model card appears on Hugging Face or Artificial Analysis lists the model, the only honest benchmark is the one you run yourself. If you want to run it on metered infrastructure, create a free key and test it against your own tasks, and check our rankings page for measured throughput on the models we already serve. When real Qwen4 Max scores land, we will update this post with the source.